
A/B testing sounds simple.
Create two versions of a page. Show one version to some visitors and the other version to everyone else. Compare the results. Keep the winner.
That basic idea is correct.
The difficult part is everything around it.
What should you test?
Which metric decides the winner?
How much traffic do you need?
How long should the experiment run?
What happens if clicks improve but revenue falls?
And perhaps most importantly: should this change be tested at all?
A/B testing is valuable because it lets you compare competing ideas using real customer behavior, not opinions.
But a good experimentation program is not about testing every button color.
It is about using experiments when there is meaningful uncertainty and enough data to learn from the result.
What A/B testing actually tells you
In an A/B test, eligible users are randomly assigned to different experiences.
For example:
- Version A: the current product page
- Version B: the same page with redesigned delivery information
Both versions run during the same period and under broadly the same external conditions.
If the experiment is implemented correctly, random assignment helps make the groups comparable.
That allows us to ask:
Did the change produce a meaningful difference in the metric we defined before launching the test?
This is more useful than releasing the new design to everyone and comparing this month with last month.
Between two different periods, many other things could have changed:
- Traffic sources
- Promotions
- Stock
- Seasonality
- Competitor activity
- Device mix
A controlled experiment helps isolate the change itself.
Not every change needs an A/B test
This is an important place to start.
Testing is useful when you have two or more reasonable options and don't know which will work better.
It is less useful when the problem is already obvious.
Fix clear defects instead of testing them
You probably do not need an experiment to decide whether to:
- Fix a broken checkout button
- Correct an inaccessible form
- Repair a payment error
- Remove an accidental duplicate Purchase event
- Fix a product image that does not load
- Correct misleading shipping information
If something is objectively broken, fix it.
Don't knowingly send half your customers into the broken version just to prove the fixed one performs better.
Testing becomes useful when the answer is uncertain
For example:
- Should delivery information appear beside Add to Cart or further down the page?
- Does a sticky mobile Add to Cart improve product-page performance?
- Which product-image treatment helps customers choose?
- Does a shorter checkout improve completion without increasing mistakes?
- Does a different category layout improve product discovery?
Those are genuine hypotheses.
Reasonable people can disagree about the answer.
That is exactly where experimentation becomes valuable.
Low traffic can make A/B testing the wrong tool
A/B testing needs enough observations to distinguish a real effect from normal randomness.
That creates a practical problem for smaller stores.
If a store receives only a few purchases each week, testing a small conversion-rate change may require an impractically long experiment.
In that situation, customer research may produce useful answers faster.
Alternatives include:
- Usability testing
- Customer interviews
- Session recordings
- Support-ticket analysis
- Analytics and funnel analysis
- Heuristic UX reviews
A/B testing is one research method.
It is not automatically the best method for every question.
Start with a problem, not an element
Weak experiments often start like this:
“Let's test a green button against a blue button.”
Why?
“Because button colors affect conversion.”
That is not much of a hypothesis.
A stronger experiment begins with an observed problem.
For example:
Mobile customers frequently open the shipping section before adding a product to cart, and support receives repeated questions about delivery times.
Now we can form a hypothesis:
If we show estimated delivery information beside the purchase controls, customers will have less uncertainty and more of them will continue toward purchase.
Then we design a variation that tests that idea.
A useful hypothesis contains three things
Observation: what problem did we find?
Change: what are we changing?
Expected effect: what behavior should change if our reasoning is correct?
This makes the experiment useful even when the variation loses.
You still learned something about the original hypothesis.
What is worth testing in eCommerce?
The highest-value experiments usually happen around important customer decisions.
| Area | Useful experiment questions |
|---|---|
| Category pages | Do filters, sorting, product-card information, or merchandising changes improve product discovery? |
| Product pages | Does a different information hierarchy reduce uncertainty and improve progression toward purchase? |
| Pricing and promotions | Does presentation make the existing offer easier to understand? |
| Product imagery | Which image sequence or format better supports evaluation? |
| Cart | Which information helps customers confidently continue to checkout? |
| Checkout | Can you remove unnecessary effort without increasing errors or operational problems? |
| Landing pages | Which message and information structure better matches campaign intent? |
Button tests have their place
CTA wording, position, size, and presentation can be worth testing when there is a reason to believe the control itself is creating confusion.
But button color should not define experimentation.
A test that changes how customers understand delivery, returns, sizing, or product differences may answer a much more valuable business question.
Choose one primary success metric
Before launching an experiment, decide what determines whether the hypothesis succeeded.
This is your primary metric.
Depending on the experiment, it might be:
- Purchase rate
- Revenue per visitor
- Checkout completion
- Add-to-cart rate
- Successful product discovery
The metric should be closely connected to the change being tested.
Do not optimize a proxy blindly
Imagine Version B increases Add to Cart by 8%.
Great.
But what if:
- Purchase rate stays unchanged
- Average order value falls
- Returns increase
Then the “winner” becomes less obvious.
This is why we also monitor secondary and guardrail metrics.
Use guardrail metrics to catch unwanted trade-offs
A guardrail metric protects something important that should not deteriorate while the primary metric improves.
For example:
| Experiment | Primary metric | Possible guardrails |
|---|---|---|
| Product-page CTA change | Add-to-cart rate | Purchase rate, revenue per visitor |
| Checkout simplification | Checkout completion | Payment failures, order errors |
| Promotion presentation | Purchase rate | Average order value, margin |
| Product recommendation change | Recommendation engagement | Revenue per visitor, checkout progression |
An experiment should not “win” because one narrow number improved while a more important business metric deteriorated.
Sample size cannot be reduced to “a few hundred visitors”
The required traffic depends on the experiment.
No universal minimum sample size exists.
Important factors include:
- The existing conversion rate
- The smallest improvement worth detecting
- The desired false-positive threshold
- The statistical power you want
- The amount of traffic assigned to each variation
Smaller effects are harder to detect
Suppose a product page converts at 5%.
Detecting a change from 5% to 7% is much easier than reliably detecting a change from 5% to 5.1%.
The second experiment generally requires far more data.
This idea is often described using the minimum detectable effect, or MDE.
Before running a test, ask:
What is the smallest change that would actually be worth acting on?
If a 0.05 percentage-point improvement would not justify the development work anyway, there is little reason to design the experiment around detecting such a tiny effect.
Statistical significance does not mean “95% sure B is better”
This is another common simplification in A/B testing guides.
In a traditional frequentist test, a 5% significance threshold does not literally mean:
“There is a 95% probability that Version B is the true winner.”
The interpretation depends on the statistical method the experimentation platform uses.
Not every modern experimentation platform uses the same statistical engine.
Some use frequentist methods.
Others use Bayesian or sequential approaches.
That is why teams should understand how their testing platform reports uncertainty, rather than translating every result into the same “95% confidence” sentence.
Do not stop simply because the dashboard turns green
Experiment results move while data is accumulating.
A variation can look excellent after the first day and lose that apparent advantage later.
Stopping whenever results look favorable can increase the chance of a bad decision, depending on the statistical methodology.
Before launch, decide:
- How the sample requirement will be determined
- How the testing platform handles repeated observation
- What business cycle needs to be covered
- What stopping rule will be used
Duration still matters
Even when enough traffic arrives quickly, there may be reasons to observe the experiment across relevant business cycles.
Customer behavior can differ between:
- Weekdays and weekends
- Paydays and ordinary periods
- Campaign and non-campaign traffic
- Different acquisition channels
But “always run for exactly two weeks” is not a universal rule either.
Experiment duration should follow the statistical plan and the business context.
Check that the experiment itself is working
Before trusting the result, check the implementation.
One useful diagnostic is whether visitors were distributed roughly according to the intended traffic allocation.
If an experiment was configured 50/50 but traffic becomes unexpectedly and substantially imbalanced, there may be an implementation problem.
This is known as a sample ratio mismatch.
Potential causes can include:
- Experiment-assignment problems
- Incorrect targeting
- Redirect behaviour
- Bots
- Technical implementation errors
A statistically impressive result is not useful if users were not assigned correctly in the first place.
Do not change the experiment halfway through
Once a test is running, avoid casually changing:
- The page design
- The hypothesis
- The traffic allocation
- The primary metric
- The audience definition
If a serious implementation problem appears, fixing and restarting the experiment may be cleaner than pretending the original and modified periods are one consistent test.
This is another reason to QA experiments carefully before launch.
Test one hypothesis, not necessarily one tiny element
You may have heard the rule:
“Only change one thing in an A/B test.”
That advice is useful when you want to isolate the effect of one specific change.
But it can become too restrictive.
Suppose your hypothesis is:
Customers hesitate because delivery information is unclear.
The variation might need to change:
- The delivery message
- Its position
- The visual treatment
Technically, several interface details changed.
But they all test one coherent hypothesis.
The important rule is:
Know what idea you are testing.
If Version B simultaneously changes the headline, price presentation, reviews, product gallery, CTA, and navigation, a win tells you the package worked but gives little information about why.
Run experiments on the right audience
An experiment should represent the customers affected by the decision.
For example, if you are changing the mobile product-page experience, mixing desktop and mobile users into one headline result may hide what happened.
Useful segmentation can include:
- Device
- Market
- New versus returning customers
- Traffic source
But be careful with post-test slicing.
If you search enough small segments after the experiment ends, you will eventually find something that looks interesting by chance.
Define important segments before the test, when they are central to the hypothesis.
Revenue experiments need business metrics
A change can increase conversion while hurting revenue.
For example, a promotion may produce:
- More orders
- Lower average order value
- Lower margin
Depending on the business, the variation may still be worse.
For eCommerce, useful metrics can include:
- Purchase conversion rate
- Revenue per visitor
- Average order value
- Gross margin where measurement allows it
- Refund or cancellation behavior
The right metric depends on what the business is actually trying to improve.
A losing test is not a failed test
Experiments are useful because our assumptions are often wrong.
If Version B performs worse, the experiment may have prevented the business from rolling a bad idea out to everyone.
If there is no meaningful difference, that can also be useful.
It may tell you that the element receiving weeks of internal debate does not materially affect customer behavior.
The valuable output of experimentation is not:
How many tests did we win?
It is:
What did we learn that changes our next decision?
Document experiments so the organization can learn
Without documentation, teams eventually repeat the same tests.
For every experiment, keep a record of:
- The problem observed
- The hypothesis
- The control
- The variation
- The primary metric
- Guardrail metrics
- The audience
- Traffic allocation
- Start and end dates
- The result
- What you concluded
- What happens next
Over time, this becomes more valuable than a folder of screenshots labeled “winning tests.”
It becomes a record of what you have learned about your customers.
A practical workflow for an eCommerce A/B test
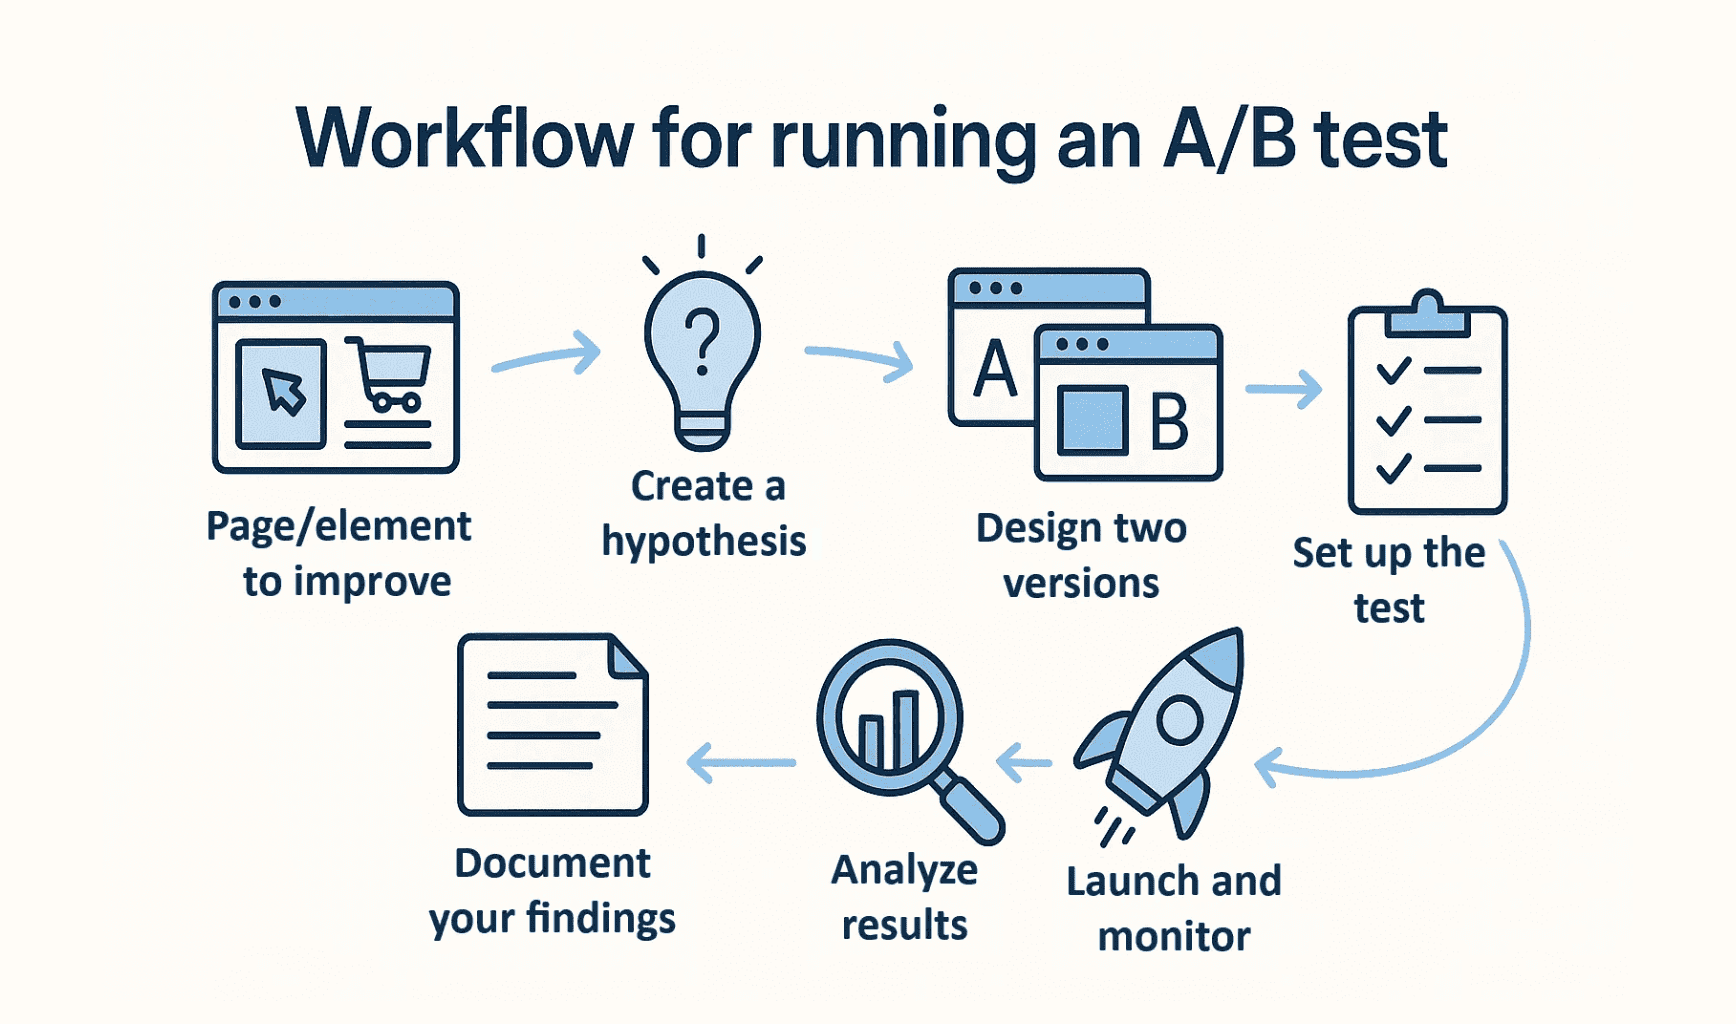
- Find a meaningful problem. Use analytics, customer feedback, usability research, support questions, or other evidence.
- Create a hypothesis. Explain what you want to change, why, and which behavior you expect to improve.
- Choose the primary metric. Define what determines success before seeing results.
- Add guardrails. Decide which important metrics must not deteriorate.
- Estimate the required sample. Use the baseline metric, minimum detectable effect, and the statistical approach used by your platform.
- Build and QA the variation. Test assignment, tracking, devices, and important customer paths.
- Launch the experiment. Use the planned audience and traffic allocation.
- Let the statistical plan determine when you have enough evidence. Don't stop just because an early result looks attractive.
- Analyze the complete outcome. Review the primary metric, guardrails, implementation health, and relevant predefined segments.
- Document the learning. Record the result, whether the variation won, lost, or made no meaningful difference.
What A/B testing tools can you use in 2026?
One part of the original A/B testing landscape has changed significantly.
Google Optimize no longer exists.
Google discontinued Optimize and Optimize 360 on September 30, 2023.
Google Analytics now supports integrations with third-party experimentation platforms rather than directly replacing Optimize.
Examples include:
- AB Tasty
- Optimizely
- VWO
Other commercial platforms and custom experimentation systems also exist, depending on the technical stack.
What matters more than the tool name
When evaluating an experimentation platform, look at:
- How users are assigned to variations
- Which statistical methodology it uses
- Sample-size and experiment-planning support
- Primary, secondary, and guardrail metrics
- Experiment health checks
- Segmentation
- Analytics integration
- Server-side or feature experimentation if needed
- Performance impact on the website
An easy visual editor is convenient.
It should not be the only reason you choose the platform.
Be careful with client-side experimentation performance
Experimentation itself can affect the customer experience.
Some client-side tools need JavaScript to decide which variation a visitor should see and then modify the page.
Poor implementation can create:
- Additional JavaScript
- Delayed rendering
- Visible flicker between control and variation
- Layout shifts
If the testing platform is making the site materially slower, that becomes part of the experiment too.
For larger or technically mature products, server-side or feature-level experimentation may be worth considering when the architecture supports it.
How we decide whether something should be A/B tested
At Creative Brackets, we would ask five questions before turning an idea into an experiment.
1. Is there a real customer or business problem?
Experiments should not exist just to fill a testing calendar.
2. Are there at least two reasonable solutions?
If one option is obviously broken, fix it.
3. Can we measure the expected effect?
The hypothesis needs a metric connected to the behavior we want to change.
4. Do we have enough traffic and conversions?
If not, qualitative research may be more useful.
5. Would the result change what we do?
If the team plans to ship Version B regardless of the result, there is little reason to run the experiment.
Experiment where uncertainty is expensive
A/B testing is not valuable because it produces more charts.
It is valuable because it can reduce the cost of being wrong.
If two reasonable checkout designs exist and the team cannot confidently predict which is better, exposing the new version to 100% of customers immediately is a large bet.
An experiment makes that bet smaller and measurable.
But experimentation has its own cost.
It requires:
- Traffic
- Development
- Analytics
- QA
- Time
- Statistical discipline
Use it where the uncertainty matters enough to justify those costs.
Test less randomly, learn more deliberately
A mature experimentation program is not measured by how many A/B tests it launches.
It is measured by whether those experiments improve decisions.
Start with evidence.
Form a hypothesis.
Choose the metric before seeing the result.
Protect important business outcomes with guardrails.
Collect enough data for the question you are asking.
And document what you learned even when the new idea loses.
That is how A/B testing turns from random optimization into a repeatable way of learning about customers.
Have a conversion problem but are not sure whether to test, redesign, or simply fix it?
Creative Brackets can review your eCommerce funnel, measurement setup, and customer friction, then identify which questions are worth experimenting on and which should be solved directly.
FAQ
1. Does every eCommerce store need A/B testing?
Every store can benefit from evidence-based decision-making, but not every store has enough traffic or conversions for useful A/B tests. Smaller stores may learn faster through usability tests, customer interviews, analytics, and other research methods until traffic increases.
2. How much traffic do I need for an A/B test?
There is no universal visitor threshold. Required sample size depends on the baseline conversion rate, the minimum effect worth detecting, traffic allocation, and the statistical methodology. Calculate the requirement for the specific experiment rather than using a rule such as “500 visitors per variation.”
3. Does 95% statistical significance mean there is a 95% chance Version B is better?
Not necessarily. That wording is not a correct general interpretation of frequentist significance, and experimentation platforms use different statistical methods. Follow the interpretation and stopping rules of the statistical methodology used by your testing platform.
4. How long should an A/B test run?
Run it long enough to meet the experiment's statistical requirements and cover relevant business variation. There is no universal one-week or two-week rule. Traffic volume, baseline conversion, expected effect, customer behavior, and the tool's statistical methodology all affect duration.
5. Should we test only one change at a time?
Test one clear hypothesis at a time. A variation can include several related design changes when they all support the same hypothesis. The more unrelated things you change at once, the harder it is to understand why the result changed.
6. What should the primary metric be?
Choose the metric most closely connected to the hypothesis and business objective. Purchase rate or revenue per visitor may be appropriate for some experiments, while a closer funnel metric such as add-to-cart can be useful for others. Use guardrails to make sure improving the primary metric does not harm a more important outcome.
7. Is Google Optimize still available?
No. Google Optimize and Optimize 360 were discontinued on September 30, 2023. Google now supports integrations between GA4 and third-party experimentation providers such as AB Tasty, Optimizely, and VWO.
8. What happens if the variation does not win?
That can still be a useful result. You may have prevented a harmful change from reaching every customer, disproved an assumption, or learned that the tested area matters less than expected. Document the finding and use it to improve the next hypothesis.
9. Should every experiment optimize conversion rate?
No. Conversion rate can ignore order value, margin, cancellations, or downstream effects. Depending on the experiment, revenue per visitor or another business metric may be more useful, while conversion rate becomes a supporting metric.
